Talkform
meta-muse-spark-1.3run 8 Sep 202693,129 tokens
Instructions
Instructions — the case's current instructions
build a typeform competitor where the backend is identical to typeform with structured questions and answers, but the frontend is purely an AI voice interview, with the AI interviewer aware of what structured data it needs to fill in for the user, but asking in a more natural conversational way. get it running including auth just ask me for the API keys for the services you need.
build a typeform competitor where the backend is identical to typeform with structured questions and answers, but the frontend is purely an AI voice interview, with the AI interviewer aware of what structured data it needs to fill in for the user, but asking in a more natural conversational way. get it running including auth just ask me for the API keys for the services you need.
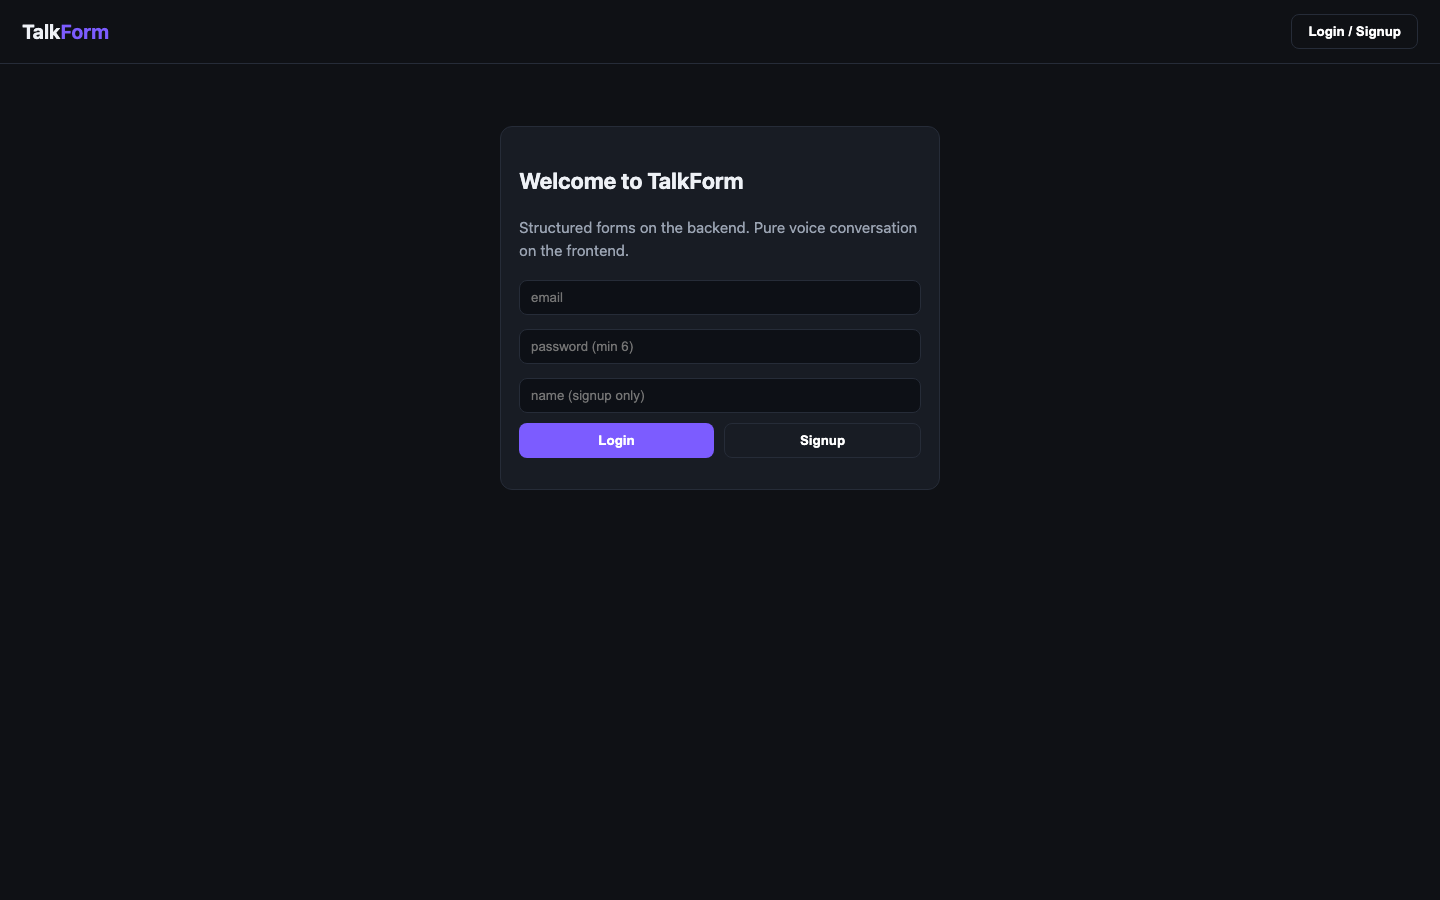
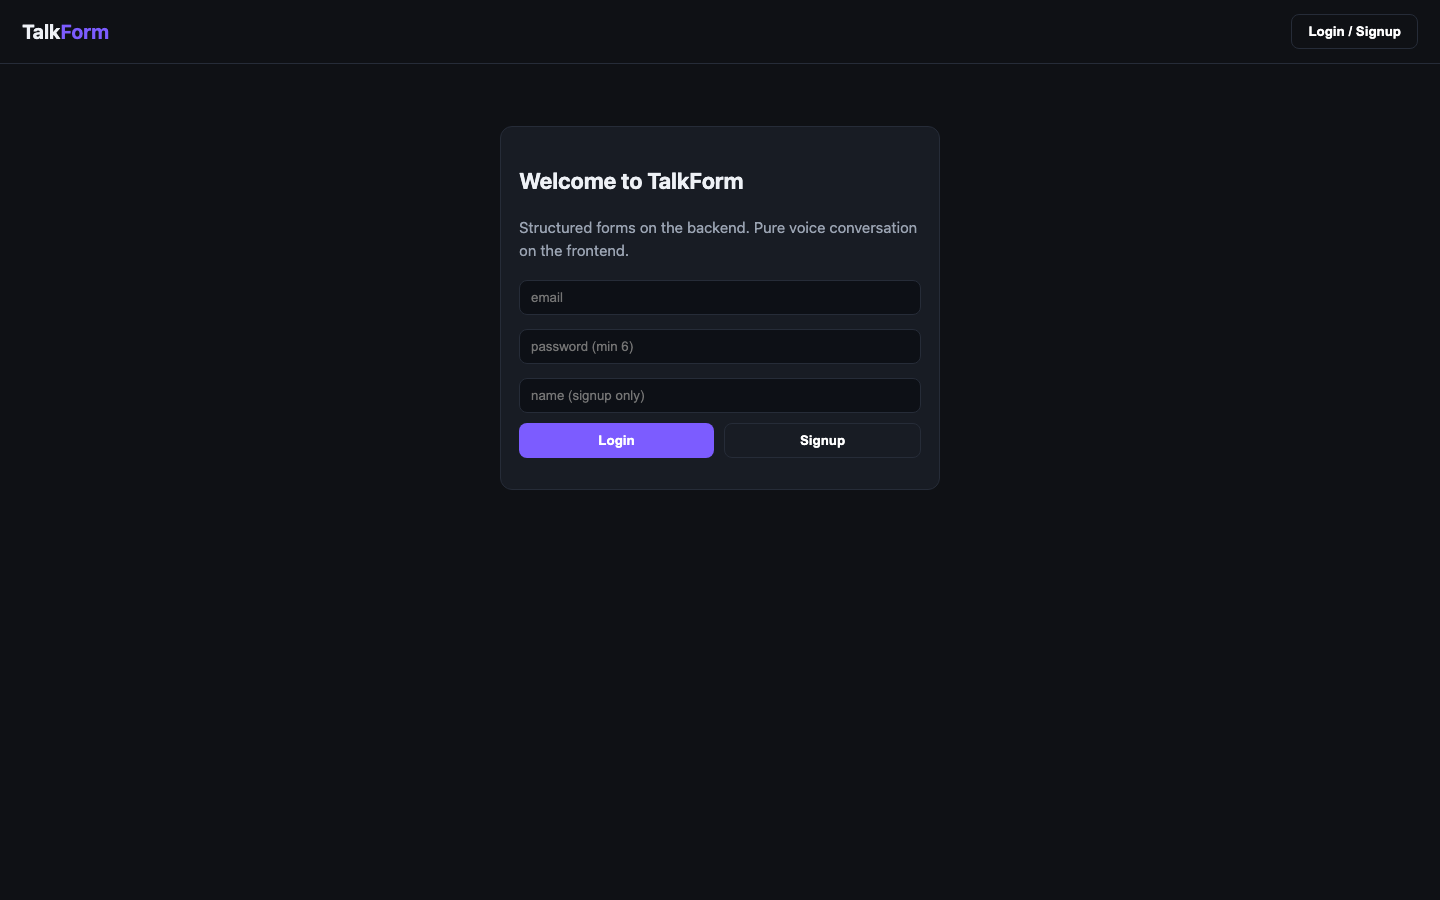
TalkForm — build complete, verified running
Built and smoke-tested a Typeform competitor in this directory: structured backend identical in shape to Typeform, frontend purely an AI voice interview. node smoke.js prints SMOKE OK (coercion + validation units, DB roundtrip, heuristic interview flow, 18-endpoint route check, frontend wiring check). See README.md to run.
Architecture
server.js— Express API. Auth (bcrypt + JWT), owner CRUD for forms/questions, publish/unpublish, response reader, public respondent endpoints, and the schema-awarePOST /api/public/forms/:share/voice-turninterviewer.db.js— SQLite via Node's built-innode:sqlite(no native build). Tables:users, forms, questions, responses, answers.public/— dependency-free SPA: auth, dashboard, question builder, voice interview (SpeechRecognition+speechSynthesis, type-in fallback, progress bar, transcript), results table + CSV.- Question kinds: short/long text, email, phone, number, single/multi choice, rating, yes_no, date — all enforced server-side on submit.
- Voice design: the interviewer knows the full schema and what's already filled, asks one paraphrased question at a time, acknowledges answers, re-asks on unparseable input, and confirms before submit. Extraction is deterministic server code; the LLM (optional) only paraphrases, and final submit re-validates.
API keys — nothing required to run; one optional upgrade
Per the contract I am not asking interactively; assumptions and key requests:
- No key needed for auth, DB, voice STT/TTS. Auth is self-contained JWT; voice uses the browser's free built-in Web Speech APIs (Chrome/Edge recommended). No Twilio/ElevenLabs/etc. required.
- Optional:
OPENAI_API_KEY(requested) — enables GPT paraphrasing in the interviewer (OPENAI_MODELdefaults togpt-4o-mini). Without it the built-in heuristic interviewer runs, and everything still works end-to-end. If you provide one, put it in.env(see.env.example) — server uses it only for reply phrasing, never for extraction. - Assumed, please confirm:
JWT_SECRET(set a long random string in production via.env); single-tenant SQLite file is fine for now (swapdb.jsfor Postgres at scale); English-only interview.
To get the keyed behavior, send me an OPENAI_API_KEY (and optionally OPENAI_MODEL) and I will wire/verify it; no other services need keys.