Mike's Checks/claude-opus-5.5/01 dashboard
01 dashboard
claude-opus-5.5Claude Codehigh effortrun 20 Sep 2026864,523 tokens
▸Instructions — what the model was asked
I want you to build a static html NPS dashboard and pick out interesting insights after doing analysis of the comments
Answer
Checks
8/10No AI-tell wordingai-wordingevery task
deliverable text contains none of the shared AI-tell phrases in bench/ai-tells.txt. Task checks may add narrower contractual bans, but must not repeat this shared floor.
shared AI-tell phrases: the world of
Page loadsrendersthis task
the dashboard loads in a headless browser with no console error and paints at least 40 characters of text. Cannot pass without Playwright installed.
Correct NPSnps-correctthis task
the page says "NPS" or "net promoter", and the NPS computed from the source CSV appears on it within 0.15. Missing source data fails closed.
Score breakdowndistribution-shownthis task
"promoter", "passive" and "detractor" all appear, and all three groups carry either their raw count (within 0.01) or their share (within 0.2 of a percentage point). Missing source data fails closed.
Working controlsinteractivethis task
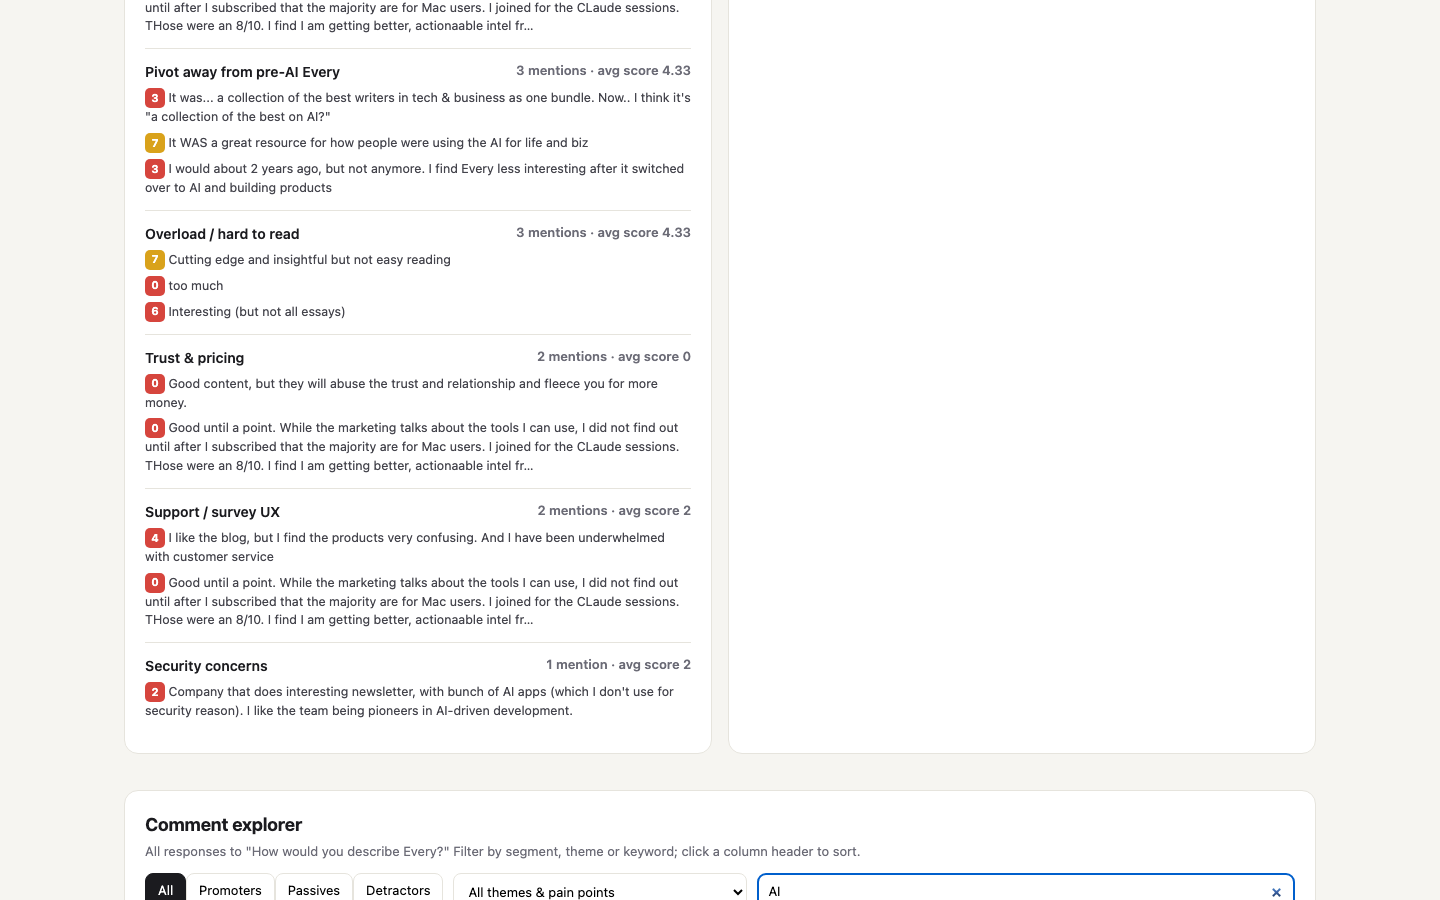
driving a real control -- text/search input, select, button or tab -- changes what the page displays. FAIL when the page could not be driven at all.
Q1Useful headlinethis task
Judge's reasoning
The h1 reads "Every · NPS & Brand Perception" — a bare category label that would sit unchanged on any product's NPS dashboard and tells the reader nothing this particular survey showed.
▸Rubric
The headline earns its place. Look at `fold.png` and read the dashboard's own top-level title/headline — the line the page leads with, not the browser tab title and not a section heading. This asks two things of one line, and FAILs if either is missing. It must (a) say what this particular data showed, and (b) be worth reading. FAIL if the headline is a bare label that would sit unchanged on any NPS dashboard for any product — "NPS Dashboard", "Every NPS Results", "Customer Feedback Analysis", "Survey Results Overview" — or if it is a naked metric restated as a title. FAIL also if it reaches for interest at the cost of accuracy: a claim the data on the page does not support. PASS if someone who read only that line would learn something true and specific about this survey, and would want to look at the rest. The reviewer's words: *"is the headline a good concise summary of the content while being interesting?"*
Q2Distinctive designthis task
Judge's reasoning
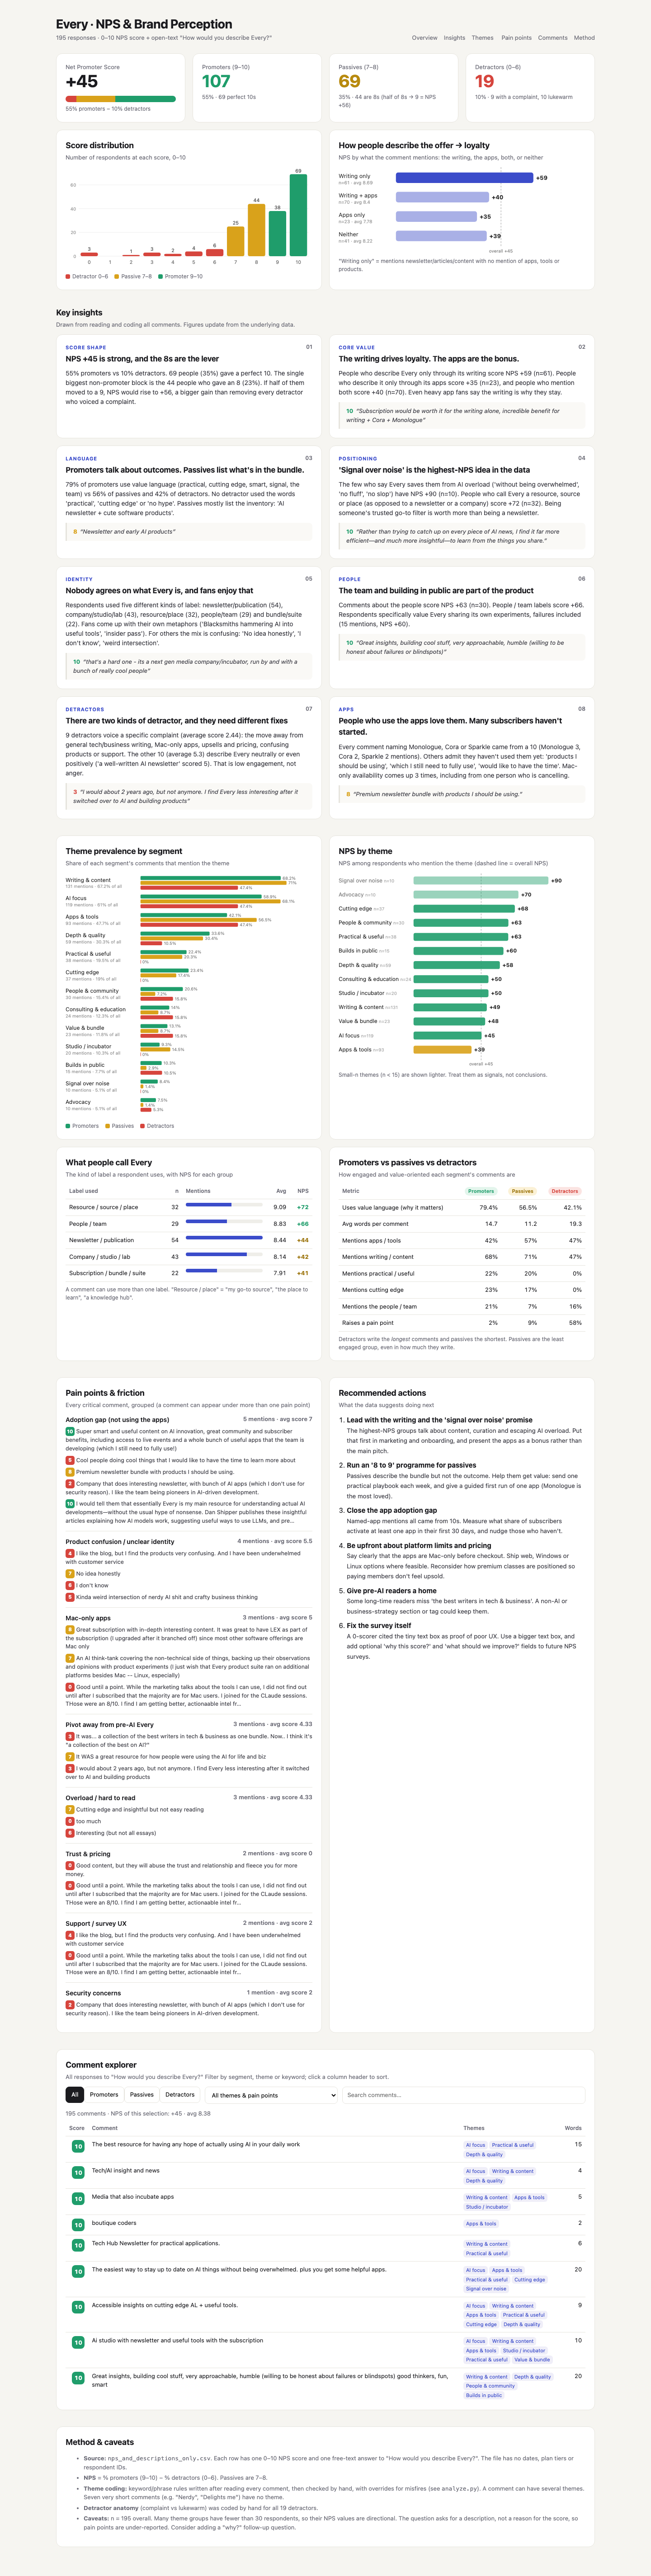
Warm off-white (#f6f5f1) background with restrained red/amber/green segment colors and plain bordered cards — no purple-on-black gradient/neon treatment.
▸Rubric
AI-slop design. Look at `fold.png` and `full.png`. FAIL if the dashboard looks like generic AI-generated design — the reviewer's words: "we should definitely weigh it down if it's purple-black dark mode," and "at the very least, like it shouldn't look like a Vibe Slop, like purple dark mode." The specific tell is a purple-on-black dark-mode treatment (purple/violet/indigo gradients, glow, neon accents on a near-black background). PASS anything that reads as a considered design, light or dark, that isn't that.
Q3Readable typographythis task
Judge's reasoning
A deliberate system sans stack with tuned letter-spacing, tabular numerals, clear size hierarchy and high-contrast ink on cream; nothing cramped, clipped, or browser-default.
▸Rubric
Typography. Look at `fold.png` and `full.png`. FAIL if the type is unconsidered or hard to read — the reviewer's words: "the typography. Like did it pick like good fonts? ... Is, is it like easy to read?" Concrete failure evidence: raw browser-default fonts, low-contrast text, cramped or overflowing/clipped text, sizes so small the numbers and comments are hard to read. PASS if fonts look deliberately chosen and the page is comfortable to read.
Q4Useful findingsthis task
Judge's reasoning
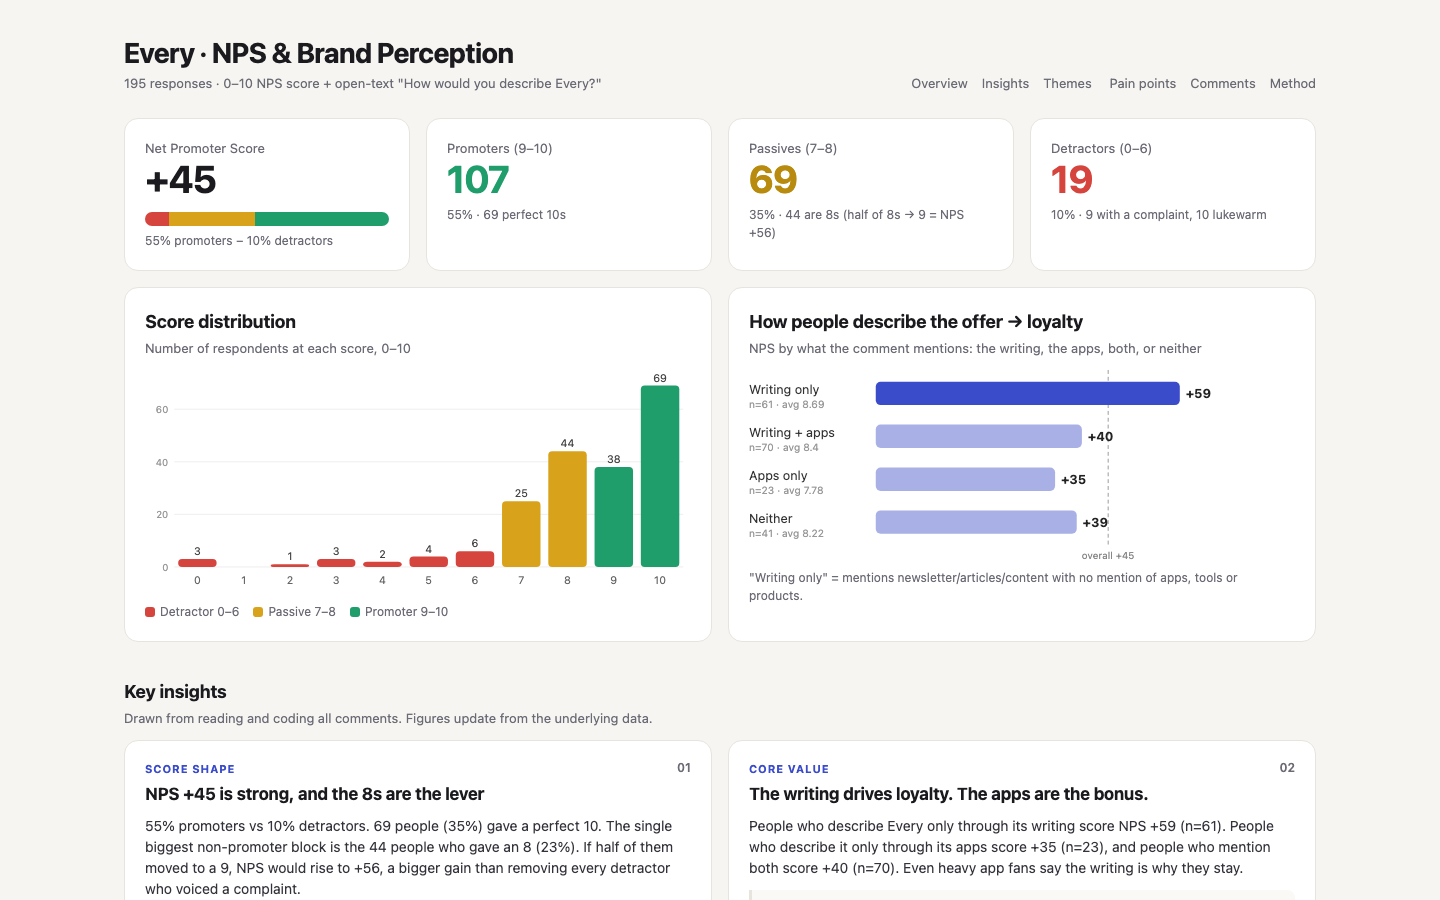
Insights name comment-derived patterns not visible in the score distribution — e.g. respondents who describe Every only through its writing score +59 vs +35 for apps-only, promoters use outcome language while passives list bundle inventory, and detractors split into 9 with specific complaints vs 10 lukewarm.
▸Rubric
Decision-useful insight. Read the insights section(s) of the dashboard. FAIL if every stated insight is arithmetic restated — counts, percentages, averages, or "X% are promoters" phrased as a finding — with nothing that would help someone decide. The bar, in the reviewer's words: "would this actually be useful for me if I was ... making a decision about whether Every is a good product or not." PASS if at least one insight names a pattern in the comments (a theme, a segment, a tension between what promoters and detractors say) that a reader could act on and that is not derivable from the score distribution alone.
Q5Key facts firstthis task
Judge's reasoning
fold.png shows the +45 NPS headline plus promoter (107/55%), passive (69/35%) and detractor (19/10%) cards and the segment bar, all without scrolling.
▸Rubric
Key information above the fold. Look at `fold.png` only. FAIL if the headline NPS number and the promoter/passive/detractor breakdown are not both visible without scrolling. The reviewer's words: "does it, does it like put the important information above the fold? ... That's the main thing for me."
Notes
1Okay, for the dashboard task, a very boring title as per usual for the recent Claude models. Like Fable also failed on this. It pulled out some good insights. Like it pulled out that the single biggest non-promoter block is 44 people who gave an 8. If half of them moved to a 9, MPS would rise quite a bit. That would be a big gain. They're removing every detractor who voiced a complaint. So that's like a really cool insight that I hadn't even seen before. So I really like that it also pulled out that the writing is what drives loyalty and the apps are just a bonus. I think that's not actually even obvious entirely of the company. And it put a really cool visualization of that. We're showing the NPS score from writing only, writing plus apps, apps only, and apps only is the lowest. So that's really cool. It had AI tells in the writing still unfortunately, and the headline wasn't that great, but otherwise this is a pretty good run.
21 Sep 2026